One system. Several signals. One coordinated decision.
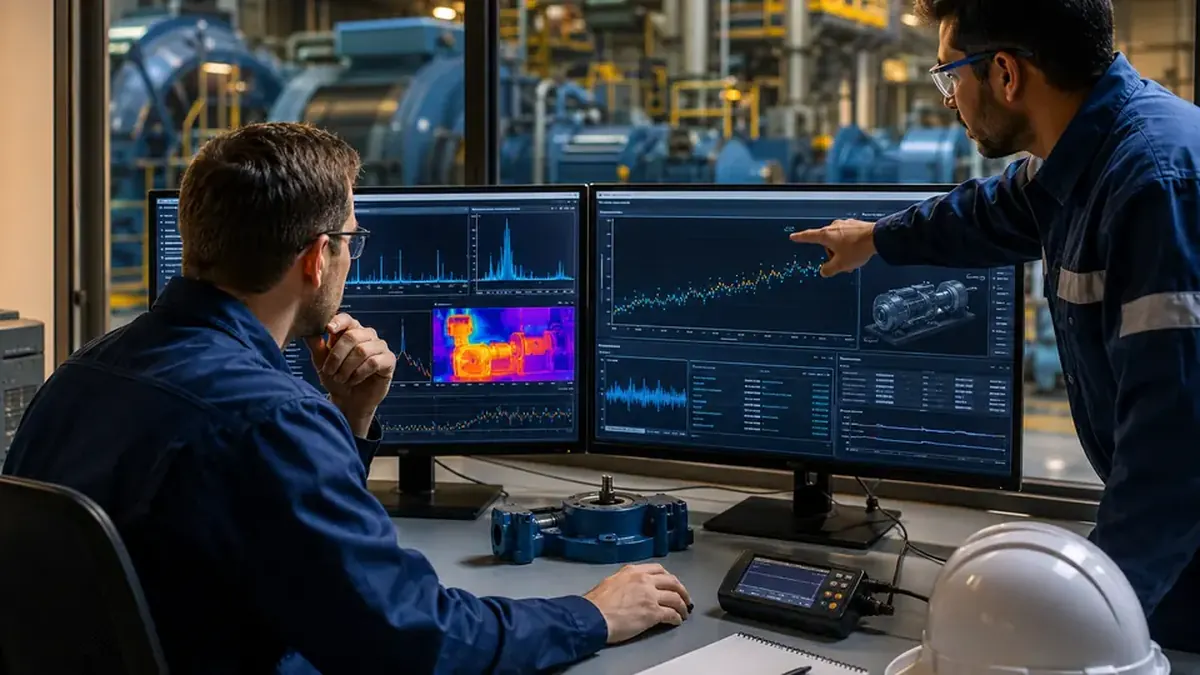
A solution combines several observations into one condition decision. It starts with the asset and credible failure modes, then selects complementary methods so one ambiguous indicator is not allowed to drive the conclusion.
For continuous condition monitoring, that means beginning with sensor and measurement selection, working in the context of critical rotating trains, and preserving enough evidence to support monitoring architecture.
Engineering boundary
A condition assessment supports maintenance decisions; it does not replace protective systems, code compliance, original-equipment-manufacturer limits, or an engineering study required by the site.
Condition record
What should support the system-level conclusion.
The asset, audience, or system boundary and the decision being supported
The relevant operating state, access conditions, source records, and known limitations
The observations or results related to baseline, alarm, and anomaly-detection strategy
The comparison, technical reasoning, confidence, priority, and alternative explanations
The owner, timing, verification method, and trigger for escalation or follow-up
Challenge the diagnosis
What reviewers should test before action.
Was the evidence collected under a representative and documented condition?
Does another indicator support—or conflict with—the first conclusion?
Could access, setup, data quality, environment, or operating state explain the result?
Is the proposed action proportionate to condition, consequence, and uncertainty?
What new evidence would confirm that the action worked?
Evidence architecture
How the signals are assembled into a defensible conclusion.
The value comes from the relationship between evidence—not the number of technologies used.
01
Identify critical assets and failure modes worth monitoring
Design sensor locations, rates, connectivity, and data context
Primary focus: Baseline, alarm, and anomaly-detection strategy. Expected record: Sensor, alarm, and analytics plan. Typical setting: Remote or difficult-access assets.
03
Establish baselines and validate alert or anomaly logic
Primary focus: Data quality and operating-state context. Expected record: Baseline and data-quality record. Typical setting: Transformers and generators.
04
Define analyst review, escalation, and maintenance response
Primary focus: Human review and response ownership. Expected record: Human-reviewed exception workflow. Typical setting: Assets with rapid failure development.
DELIVERABLES
Typical outputs
Monitoring architecture
Sensor, alarm, and analytics plan
Baseline and data-quality record
Human-reviewed exception workflow
APPLICATIONS
Typical assets
Critical rotating trains
Remote or difficult-access assets
Transformers and generators
Assets with rapid failure development
SYSTEM INSIGHT
AI and Machine Learning can surface unfamiliar patterns earlier, but an alert becomes useful only after data quality, operating context, and engineering judgment are applied.